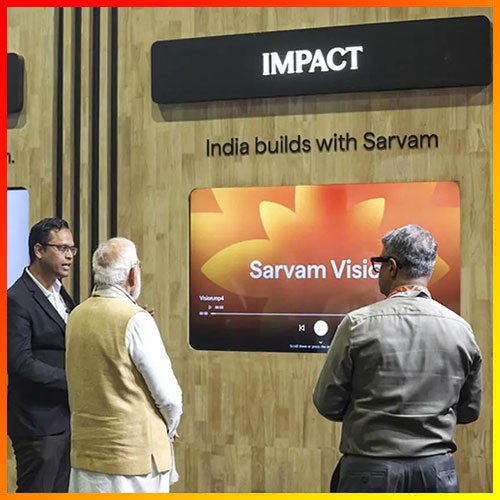
Bengaluru-based AI startup Sarvam AI announced the launch of two new large language models, a 30-billion-parameter model and a 105-billion-parameter model, both trained from scratch, positioning them within India’s broader push to build sovereign AI capabilities.
The startup announced the models at the India AI Impact Summit in Delhi and said both models use a mixture-of-experts, MoE, architecture designed to improve efficiency while maintaining performance across reasoning, programming and tool-use tasks.
“Large language models, we have, of course, been building models across a 3-billion-parameter dense model, but it is important to scale up, and there are two other models that we trained and are talking about releasing today. One is Sarvam 30 Billion,” said Pratyush Kumar, cofounder of Sarvam.
The 30B model activates only 1 billion parameters per token, despite having 30 billion parameters overall.
“It is actually a mixture-of-experts model, we have a 30-billion-parameter model, but in generating every output token, it only activates 1 billion parameters,” Kumar said. “If you look at thinking budget, Sarvam 30B significantly outperforms both at the 8K and 16K scales compared to the latest models released at the same size.”
The model supports a 32,000-token context window and was trained on 16 trillion tokens. Kumar said efficiency remains central to the company’s thesis.
Sarvam also unveiled a 105-billion-parameter MoE model with 9 billion activated parameters and a 128,000-token context window, designed for more complex reasoning and agentic tasks.
“We trained a 105-billion-parameter model, it is also designed to do complex reasoning tasks very well,” Kumar said.
He compared the model’s performance with larger global systems.
“At 105 billion parameters, on most benchmarks this model beats DeepSeek R1 released a year ago, which was a 600-billion-parameter model.”