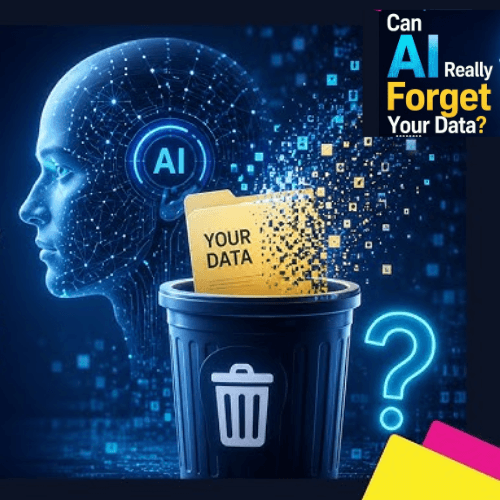
As Large Language Models (LLMs) become central to business and consumer applications, an important question is gaining attention: can AI truly forget your data?
The answer depends on how the information is stored and used within the system.
When users interact with an LLM, data is typically handled in two ways.
First, through the context window, where information is temporarily used during a conversation and can be deleted when the session ends.
Second, data may be incorporated into training datasets that help shape the model's behaviour over time.
For chat histories, stored files, and Retrieval-Augmented Generation (RAG) databases, deletion is relatively straightforward.
Organizations can remove records, delete documents, and prevent future access.
However, once information becomes part of a model's trained parameters, removing its influence becomes significantly more complex.
Researchers are actively exploring a new field called "Machine Unlearning," which aims to selectively erase the impact of specific data from trained AI models.
While promising, the technology remains in its early stages and is not yet practical for large-scale deployment.
Regulations such as the GDPR in Europe and India's DPDP Act 2023 grant individuals the right to request data deletion.
While AI providers can remove stored records and exclude data from future training, completely erasing information already embedded within model weights remains one of the most difficult and unresolved challenges in artificial intelligence today.
Technology Disruption
Is It Possible for AI to Forget Your Data?
Join the Conversation
Loading comments…
Share your thoughts on this story. Comments are moderated before they appear.
Be respectful. Comments are reviewed before publication, and spam or abusive language will be removed.